MySQL 8.4 Release Notes
BLACKHOLE 存储引擎充当一个 “黑洞”,它接受数据但会丢弃数据,而不存储数据。检索总是返回空结果:The BLACKHOLE storage engine acts as a
“black hole” that accepts data but throws it away and
does not store it. Retrievals always return an empty result:
mysql>CREATE TABLE test(i INT, c CHAR(10)) ENGINE = BLACKHOLE;Query OK, 0 rows affected (0.03 sec) mysql>INSERT INTO test VALUES(1,'record one'),(2,'record two');Query OK, 2 rows affected (0.00 sec) Records: 2 Duplicates: 0 Warnings: 0 mysql>SELECT * FROM test;Empty set (0.00 sec)
如果你从源码构建 MySQL,要启用 BLACKHOLE 存储引擎,请使用 CMake 并传递 -DWITH_BLACKHOLE_STORAGE_ENGINE 选项。To enable the BLACKHOLE storage engine if you
build MySQL from source, invoke CMake with the
-DWITH_BLACKHOLE_STORAGE_ENGINE
option.
要查看 BLACKHOLE 引擎的源代码,请在 MySQL 源代码分发版的 sql 目录中查找。To examine the source for the BLACKHOLE engine,
look in the sql directory of a MySQL source
distribution.
当你创建一个 BLACKHOLE 表时,服务器会在全局数据字典中创建表定义。该表没有关联的文件。When you create a BLACKHOLE table, the server
creates the table definition in the global data dictionary. There
are no files associated with the table.
BLACKHOLE 存储引擎支持各种索引。也就是说,你可以在表定义中包含索引声明。The BLACKHOLE storage engine supports all kinds
of indexes. That is, you can include index declarations in the table
definition.
最大键长度为 3072 字节。The maximum key length is 3072 bytes.
BLACKHOLE 存储引擎不支持分区。The BLACKHOLE storage engine does not support
partitioning.
你可以使用 BLACKHOLE 语句检查 SHOW
ENGINES 存储引擎是否可用。You can check whether the BLACKHOLE storage
engine is available with the SHOW
ENGINES statement.
插入到 BLACKHOLE 表的数据不会被存储,但如果启用了基于语句的二进制日志,SQL 语句会被记录并复制到从服务器上。这可以用作中继或过滤机制。Inserts into a BLACKHOLE table do not store any
data, but if statement based binary logging is enabled, the SQL
statements are logged and replicated to replica servers. This can be
useful as a repeater or filter mechanism.
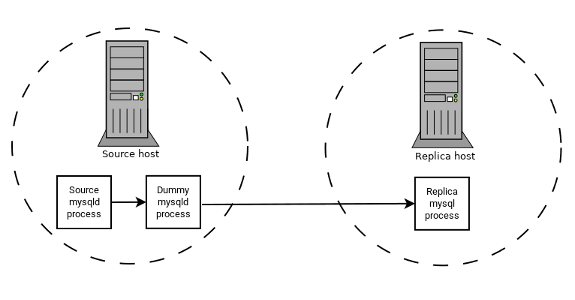
假设您的应用程序需要副本端的过滤规则,但先将所有二进制日志数据传输到副本会导致流量过大。在这种情况下,可以在复制源服务器上设置一个“虚拟”副本进程,其默认存储引擎为BLACKHOLE,如下所示:Suppose that your application requires replica-side filtering rules,
but transferring all binary log data to the replica first results in
too much traffic. In such a case, it is possible to set up on the
replication source server a “dummy” replica process
whose default storage engine is BLACKHOLE,
depicted as follows:
源写入其二进制日志。“dummy” mysqld 进程充当副本,应用所需组合的 replicate-do-* 和 replicate-ignore-* 规则,并写入其自己的新过滤二进制日志。(参见 第 19.1.6 节,“复制和二进制日志选项及变量”。)此过滤日志提供给副本。The source writes to its binary log. The “dummy”
mysqld process acts as a replica, applying the
desired combination of replicate-do-* and
replicate-ignore-* rules, and writes a new,
filtered binary log of its own. (See
Section 19.1.6, “Replication and Binary Logging Options and Variables”.) This filtered log is
provided to the replica.
这个虚拟进程实际上并不存储任何数据,因此在复制源服务器上运行额外的 mysqld 进程时几乎不会产生处理开销。这种类型的设置可以通过增加更多副本来重复进行。The dummy process does not actually store any data, so there is little processing overhead incurred by running the additional mysqld process on the replication source server. This type of setup can be repeated with additional replicas.
INSERT 触发器在 BLACKHOLE 表中可以按预期工作。然而,因为 BLACKHOLE 表实际上不存储任何数据,UPDATE 和 DELETE 触发器不会被激活:触发器定义中的 FOR EACH ROW 子句不适用,因为没有行。INSERT triggers for
BLACKHOLE tables work as expected. However,
because the BLACKHOLE table does not actually
store any data, UPDATE and
DELETE triggers are not activated:
The FOR EACH ROW clause in the trigger definition
does not apply because there are no rows.
BLACKHOLE 存储引擎的其他可能用途包括:Other possible uses for the BLACKHOLE storage
engine include:
验证转储文件的语法。Verification of dump file syntax.
通过比较使用
BLACKHOLE启用和未启用二进制日志的性能,测量二进制日志带来的开销。Measurement of the overhead from binary logging, by comparing performance usingBLACKHOLEwith and without binary logging enabled.BLACKHOLE本质上是一个“无操作”存储引擎,因此它可以用于查找与存储引擎本身无关的性能瓶颈。BLACKHOLEis essentially a “no-op” storage engine, so it could be used for finding performance bottlenecks not related to the storage engine itself.
BLACKHOLE 引擎是事务感知的,这意味着已提交的事务会写入二进制日志,而回滚的事务则不会。The BLACKHOLE engine is transaction-aware, in the
sense that committed transactions are written to the binary log and
rolled-back transactions are not.
Blackhole 引擎与自增列Blackhole Engine and Auto Increment Columns
BLACKHOLE 引擎是一个无操作引擎。对使用 BLACKHOLE 的表执行的任何操作都没有效果。在考虑自增主键列的行为时应牢记这一点。该引擎不会自动增加字段值,也不会保留自增字段状态。这在复制中具有重要影响。The BLACKHOLE engine is a no-op engine. Any
operations performed on a table using BLACKHOLE
have no effect. This should be borne in mind when considering the
behavior of primary key columns that auto increment. The engine does
not automatically increment field values, and does not retain auto
increment field state. This has important implications in
replication.
考虑以下复制场景,其中满足以下三个条件:Consider the following replication scenario where all three of the following conditions apply:
在源服务器上,有一个黑洞表,其自增字段为主键。On a source server there is a blackhole table with an auto increment field that is a primary key.
在副本服务器上,存在同样的表,但使用的是 MyISAM 引擎。On a replica the same table exists but using the MyISAM engine.
在源表中执行插入操作时,没有在
INSERT语句中显式设置自增值,也没有使用SET INSERT_ID语句。Inserts are performed into the source's table without explicitly setting the auto increment value in theINSERTstatement itself or through using aSET INSERT_IDstatement.
在这种情况下,复制会因主键列重复条目错误而失败。In this scenario replication fails with a duplicate entry error on the primary key column.
在基于语句的复制中,事件上下文中 INSERT_ID 的值始终相同。因此,复制因为尝试插入具有主键列重复值的行而失败。In statement based replication, the value of
INSERT_ID in the context event is always the
same. Replication therefore fails due to trying insert a row with a
duplicate value for a primary key column.
在基于行的复制中,引擎返回的行值在每次插入时总是相同的。这会导致副本尝试使用主键列的相同值重放两个插入日志条目,从而导致复制失败。In row based replication, the value that the engine returns for the row always be the same for each insert. This results in the replica attempting to replay two insert log entries using the same value for the primary key column, and so replication fails.
列过滤Column Filtering
使用基于行的复制时(binlog_format=ROW),支持副本表缺少最后几列的情况,如第 19.5.1.9 节,“源和副本表定义不同的复制”所述。When using row-based replication,
(binlog_format=ROW), a replica
where the last columns are missing from a table is supported, as
described in the section
Section 19.5.1.9, “Replication with Differing Table Definitions on Source and Replica”.
此过滤在副本端工作,即在列被过滤掉之前,它们会被复制到副本中。有至少两种情况不希望将列复制到副本:This filtering works on the replica side, that is, the columns are copied to the replica before they are filtered out. There are at least two cases where it is not desirable to copy the columns to the replica:
如果数据是机密的,则副本服务器不应该访问这些数据。If the data is confidential, so the replica server should not have access to it.
如果源有许多副本,则在发送到副本之前进行过滤可能减少网络流量。If the source has many replicas, filtering before sending to the replicas may reduce network traffic.
源列过滤可以使用BLACKHOLE引擎实现。这与源表过滤的实现方式类似——使用BLACKHOLE引擎以及--replicate-do-table或--replicate-ignore-table选项。Source column filtering can be achieved using the
BLACKHOLE engine. This is carried out in a way
similar to how source table filtering is achieved - by using the
BLACKHOLE engine and the
--replicate-do-table or
--replicate-ignore-table option.
源的设置为:The setup for the source is:
CREATE TABLE t1 (public_col_1, ..., public_col_N,
                 secret_col_1, ..., secret_col_M) ENGINE=MyISAM;
受信任副本的设置为:The setup for the trusted replica is:
CREATE TABLE t1 (public_col_1, ..., public_col_N) ENGINE=BLACKHOLE;
不受信任副本的设置为:The setup for the untrusted replica is:
CREATE TABLE t1 (public_col_1, ..., public_col_N) ENGINE=MyISAM;