MySQL 8.4 Release Notes
本节讨论在使用 NDB 集群复制时已知的问题或疑问。This section discusses known problems or issues when using replication with NDB Cluster.
源与副本之间连接丢失。 连接丢失可能发生在源集群 SQL 节点与副本集群 SQL 节点之间,也可能发生在源 SQL 节点与源集群的数据节点之间。在后一种情况下,这不仅可能是由于物理连接丢失(例如网线断开)引起的,还可能是由于数据节点事件缓冲区溢出;如果 SQL 节点响应过慢,它可能会被集群移除(这一点可以通过调整 MaxBufferedEpochs 和 TimeBetweenEpochs 配置参数在一定程度上控制)。如果发生这种情况,新数据可能完全被插入到源集群中而不会记录在源 SQL 节点的二进制日志中。因此,为了保证高可用性,保持备份复制通道、监控主通道,并在必要时切换到辅助复制通道以保持副本集群与源同步是极其重要的。NDB Cluster 并未设计为自行执行此类监控;为此,需要外部应用程序。Loss of connection between source and replica.
A loss of connection can occur either between the source cluster
SQL node and the replica cluster SQL node, or between the source
SQL node and the data nodes of the source cluster. In the latter
case, this can occur not only as a result of loss of physical
connection (for example, a broken network cable), but due to the
overflow of data node event buffers; if the SQL node is too slow
to respond, it may be dropped by the cluster (this is
controllable to some degree by adjusting the
MaxBufferedEpochs and
TimeBetweenEpochs
configuration parameters). If this occurs, it is
entirely possible for new data to be inserted into the source
cluster without being recorded in the source SQL node's
binary log. For this reason, to guarantee high
availability, it is extremely important to maintain a backup
replication channel, to monitor the primary channel, and to fail
over to the secondary replication channel when necessary to keep
the replica cluster synchronized with the source. NDB Cluster is
not designed to perform such monitoring on its own; for this, an
external application is required.
当源 SQL 节点连接或重新连接到源集群时,会触发一个 “gap” 事件。(gap 事件是一种 “事故事件,” 表示会影响数据库内容但不易表示为一组更改的事件。事故的示例包括服务器故障、数据库重新同步、某些软件更新和某些硬件更改。)当副本在复制日志中遇到 gap 时,会以错误消息停止。该消息可在 SHOW REPLICA STATUS 的输出中查看, 表明 SQL 线程因在复制流中记录的事故而停止,需要人工干预。有关如何处理这种情况的更多信息,请参见 第 25.7.8 节,“使用 NDB 集群复制实现故障切换”。
The source SQL node issues a “gap” event when
connecting or reconnecting to the source cluster. (A gap event is
a type of “incident event,” which indicates an
incident that occurs that affects the contents of the database but
that cannot easily be represented as a set of changes. Examples of
incidents are server failures, database resynchronization, some
software updates, and some hardware changes.) When the replica
encounters a gap in the replication log, it stops with an error
message. This message is available in the output of
SHOW REPLICA STATUS, and indicates
that the SQL thread has stopped due to an incident registered in
the replication stream, and that manual intervention is required.
See Section 25.7.8, “Implementing Failover with NDB Cluster Replication”, for more
information about what to do in such circumstances.
Important
由于 NDB 集群本身并未设计为监控复制状态或提供故障切换,如果副本服务器或集群需要高可用性,那么您必须设置多个复制通道,监控主复制通道上的源 mysqld,并在必要时准备切换到备用通道。这必须手动完成,或者可能通过第三方应用程序实现。有关实现此类设置的信息,请参阅第 25.7.7 节,“使用两个复制通道进行 NDB 集群复制” 和 第 25.7.8 节,“使用 NDB 集群复制实现故障切换”。Because NDB Cluster is not designed on its own to monitor replication status or provide failover, if high availability is a requirement for the replica server or cluster, then you must set up multiple replication lines, monitor the source mysqld on the primary replication line, and be prepared fail over to a secondary line if and as necessary. This must be done manually, or possibly by means of a third-party application. For information about implementing this type of setup, see Section 25.7.7, “Using Two Replication Channels for NDB Cluster Replication”, and Section 25.7.8, “Implementing Failover with NDB Cluster Replication”.
如果您从独立的 MySQL 服务器复制到 NDB 集群,通常一个通道就足够了。If you are replicating from a standalone MySQL server to an NDB Cluster, one channel is usually sufficient.
Circular replication. NDB Cluster Replication supports circular replication, as shown in the next example. The replication setup involves three NDB Clusters numbered 1, 2, and 3, in which Cluster 1 acts as the replication source for Cluster 2, Cluster 2 acts as the source for Cluster 3, and Cluster 3 acts as the source for Cluster 1, thus completing the circle. Each NDB Cluster has two SQL nodes, with SQL nodes A and B belonging to Cluster 1, SQL nodes C and D belonging to Cluster 2, and SQL nodes E and F belonging to Cluster 3.
只要满足以下条件,就支持使用这些集群进行循环复制:Circular replication using these clusters is supported as long as the following conditions are met:
所有源集群和副本集群上的 SQL 节点都是相同的。The SQL nodes on all source and replica clusters are the same.
所有作为源和副本的 SQL 节点都启用了系统变量
log_replica_updates。All SQL nodes acting as sources and replicas are started with the system variablelog_replica_updatesenabled.
这种类型的循环复制设置如下图所示:This type of circular replication setup is shown in the following diagram:
图 25.11 所有源同时为副本的 NDB 集群循环复制Figure 25.11 NDB Cluster Circular Replication With All Sources As Replicas
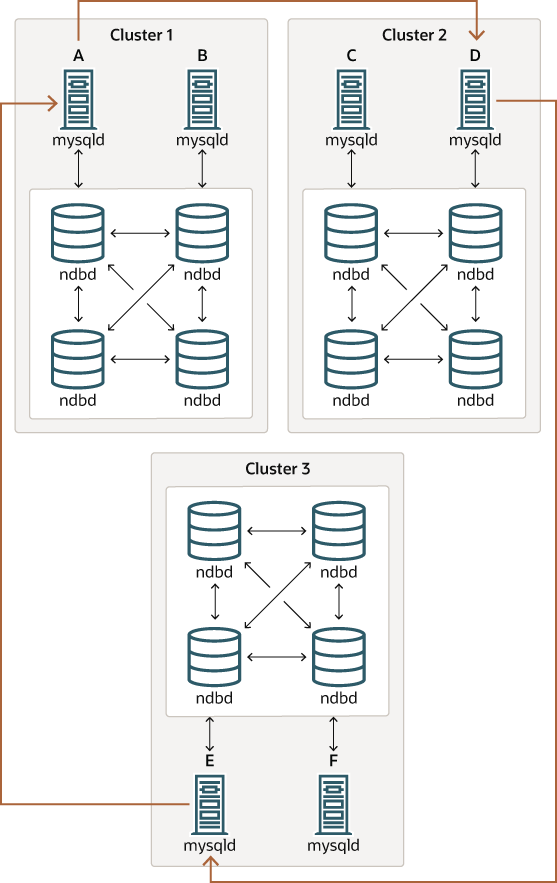
在此场景中,第 1 集群中的 SQL 节点 A 向第 2 集群中的 SQL 节点 C 复制;SQL 节点 C 向第 3 集群中的 SQL 节点 E 复制;SQL 节点 E 向 SQL 节点 A 复制。换句话说,复制线路(图中由弯曲箭头表示)直接连接所有用作源和副本的 SQL 节点。In this scenario, SQL node A in Cluster 1 replicates to SQL node C in Cluster 2; SQL node C replicates to SQL node E in Cluster 3; SQL node E replicates to SQL node A. In other words, the replication line (indicated by the curved arrows in the diagram) directly connects all SQL nodes used as sources and replicas.
同样,也可以设置循环复制,其中并非所有源 SQL 节点也作为副本,如下所示:It should also be possible to set up circular replication in which not all source SQL nodes are also replicas, as shown here:
图 25.12 当并非所有源都是副本时的 NDB 集群环形复制Figure 25.12 NDB Cluster Circular Replication Where Not All Sources Are Replicas
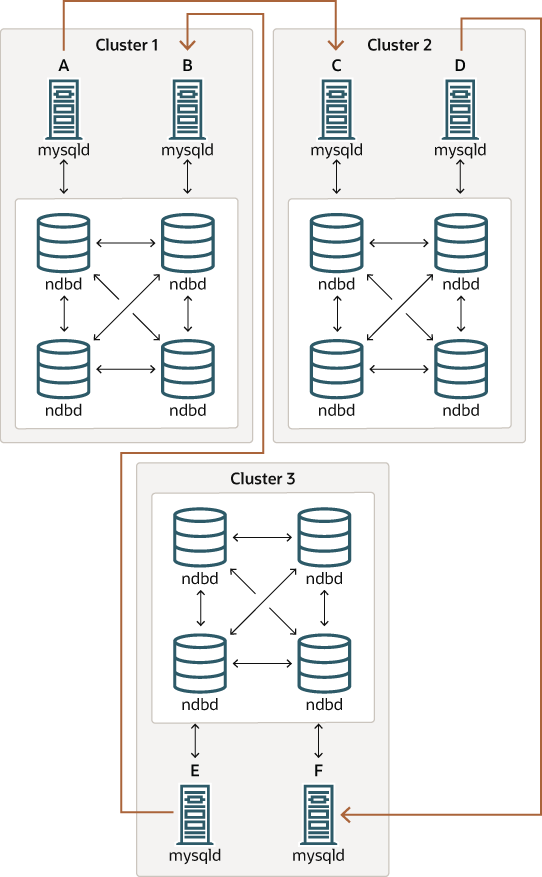
In this case, different SQL nodes in each cluster are used as
sources and replicas. However, you must 在多线程系统中
start any of the SQL nodes with the
log_replica_updates system
variable enabled. This type of circular replication scheme for NDB
Cluster, in which the line of replication (again indicated by the
curved arrows in the diagram) is discontinuous, should be
possible, but it should be noted that it has not yet been
thoroughly tested and must therefore still be considered
experimental.In this case, different SQL nodes in each cluster are used as
sources and replicas. However, you must not
start any of the SQL nodes with the
log_replica_updates system
variable enabled. This type of circular replication scheme for NDB
Cluster, in which the line of replication (again indicated by the
curved arrows in the diagram) is discontinuous, should be
possible, but it should be noted that it has not yet been
thoroughly tested and must therefore still be considered
experimental.
Note
NDB 存储引擎使用 幂等执行模式,它会抑制可能导致 NDB Cluster 循环复制中断的重复键和其他错误。这相当于将系统变量 replica_exec_mode 的全局值设置为 IDEMPOTENT,尽管在 NDB Cluster 复制中这不是必须的,因为 NDB Cluster 会自动设置该变量,并忽略任何显式设置的尝试。The NDB storage engine uses
idempotent execution mode,
which suppresses duplicate-key and other errors that otherwise
break circular replication of NDB Cluster. This is equivalent to
setting the global value of the system variable
replica_exec_mode to
IDEMPOTENT, although this is not necessary in
NDB Cluster replication, since NDB Cluster sets this variable
automatically and ignores any attempts to set it explicitly.
NDB 集群复制和主键。 在节点故障的情况下,如果没有主键的 NDB 表进行复制,仍然可能会发生错误,因为在这种情况下可能会插入重复的行。因此,强烈建议所有正在复制的 NDB 表都具有明确的主键。NDB Cluster replication and primary keys.
In the event of a node failure, errors in replication of
NDB tables without primary keys can
still occur, due to the possibility of duplicate rows being
inserted in such cases. For this reason, it is highly
recommended that all NDB tables
being replicated have explicit primary keys.
NDB 集群复制与唯一键。 在较旧版本的 NDB 集群中,更新 NDB 表的唯一键列的操作在复制时可能会导致重复键错误。通过将唯一键检查延迟到所有表行更新完成之后,可以解决 NDB 表之间的复制问题。NDB Cluster Replication and Unique Keys.
In older versions of NDB Cluster, operations that updated values
of unique key columns of NDB tables
could result in duplicate-key errors when replicated. This issue
is solved for replication between
NDB tables by deferring unique key
checks until after all table row updates have been performed.
以这种方式延迟约束目前仅由NDB支持。因此,从NDB复制到不同存储引擎(例如InnoDB或MyISAM)时的唯一键更新仍然不受支持。Deferring constraints in this way is currently supported only by
NDB. Thus, updates of unique keys
when replicating from NDB to a
different storage engine such as
InnoDB or
MyISAM are still not supported.
在没有延迟检查唯一键更新的情况下进行复制时遇到的问题,可以通过使用 NDB 表,例如 t,在源端创建并填充(并传输到不支持延迟唯一键更新的副本)来说明,如下所示:The problem encountered when replicating without deferred checking
of unique key updates can be illustrated using
NDB table such as
t, is created and populated on the source (and
transmitted to a replica that does not support deferred unique key
updates) as shown here:
CREATE TABLE t (
    p INT PRIMARY KEY,
    c INT,
    UNIQUE KEY u (c)
)   ENGINE NDB;

INSERT INTO t
    VALUES (1,1), (2,2), (3,3), (4,4), (5,5);
在 t 上执行以下 UPDATE 语句在源端成功,因为受影响的行按照 ORDER BY 选项确定的顺序进行处理,并在整个表上执行:The following UPDATE statement on
t succeeds on the source, since the rows
affected are processed in the order determined by the
ORDER BY option, performed over the entire
table:
UPDATE t SET c = c - 1 ORDER BY p;
相同的语句在副本上会因重复键错误或其他约束违规而失败,因为行更新的顺序是一次对一个分区执行的,而不是对整个表执行的。The same statement fails with a duplicate key error or other constraint violation on the replica, because the ordering of the row updates is performed for one partition at a time, rather than for the table as a whole.
Note
每个 NDB 表在创建时都会按键隐式分区。更多信息请参见 26.2.5 节,“KEY 分区”。Every NDB table is implicitly
partitioned by key when it is created. See
Section 26.2.5, “KEY Partitioning”, for more information.
不支持 GTID。 使用全局事务 ID 的复制与 NDB 存储引擎不兼容,也不被支持。启用 GTID 很可能会导致 NDB 集群复制失败。GTIDs not supported.
Replication using global transaction IDs is not compatible with
the NDB storage engine, and is not supported.
Enabling GTIDs is likely to cause NDB Cluster Replication to
fail.
使用 --initial 重启。 使用 --initial 选项重启集群会导致 GCI 和 epoch 编号序列从 0 开始重新计数。 (这通常适用于 NDB Cluster,不仅限于涉及 Cluster 的复制场景。)在这种情况下,参与复制的 MySQL 服务器应当被重启。之后,你应使用 RESET BINARY LOGS AND GTIDS 以及 RESET REPLICA 语句,分别清除无效的 ndb_binlog_index 表和 ndb_apply_status 表。Restarting with --initial.
Restarting the cluster with the
--initial option causes the
sequence of GCI and epoch numbers to start over from
0. (This is generally true of NDB Cluster and
not limited to replication scenarios involving Cluster.) The
MySQL servers involved in replication should in this case be
restarted. After this, you should use the
RESET BINARY LOGS AND GTIDS and
RESET REPLICA statements to clear
the invalid ndb_binlog_index and
ndb_apply_status tables, respectively.
从 NDB 到其他存储引擎的复制。 可以将源上的 NDB 表复制到副本上使用不同存储引擎的表,但需考虑此处列出的限制:Replication from NDB to other storage engines.
It is possible to replicate an NDB
table on the source to a table using a different storage engine
on the replica, taking into account the restrictions listed
here:
不支持多源和循环复制(为了使其工作,源和副本上的表都必须使用
NDB存储引擎)。Multi-source and circular replication are not supported (tables on both the source and the replica must use theNDBstorage engine for this to work).在副本上使用不记录二进制日志的存储引擎需要特殊处理。Using a storage engine which does not perform binary logging for tables on the replica requires special handling.
在副本上使用非事务存储引擎的表也需要特殊处理。Use of a nontransactional storage engine for tables on the replica also requires special handling.
源 mysqld 必须以
--ndb-log-update-as-write=0或--ndb-log-update-as-write=OFF启动。The source mysqld must be started with--ndb-log-update-as-write=0or--ndb-log-update-as-write=OFF.
接下来的几段提供了关于刚才描述的每个问题的更多信息。The next few paragraphs provide additional information about each of the issues just described.
在将 NDB 复制到其他存储引擎时,不支持多个源。 对于从 NDB 到不同存储引擎的复制,两个数据库之间的关系必须是一对一。这意味着 NDB Cluster 与其他存储引擎之间不支持双向或循环复制。Multiple sources not supported when replicating NDB to other storage
engines.
For replication from NDB to a
different storage engine, the relationship between the two
databases must be one-to-one. This means that bidirectional or
circular replication is not supported between NDB Cluster and
other storage engines.
此外,在 NDB 与不同存储引擎之间进行复制时,不可能配置多个复制通道。(NDB Cluster 数据库 可以 同时复制到多个 NDB Cluster 数据库。)如果源使用 NDB 表,仍然可以让多个 MySQL 服务器维护所有更改的二进制日志,但为了让副本更换源(故障切换),必须在副本上明确地定义新的源-副本关系。In addition, it is not possible to configure more than one
replication channel when replicating between
NDB and a different storage engine.
(An NDB Cluster database can simultaneously
replicate to multiple NDB Cluster databases.) If the source uses
NDB tables, it is still possible to
have more than one MySQL Server maintain a binary log of all
changes, but for the replica to change sources (fail over), the
new source-replica relationship must be explicitly defined on the
replica.
将 NDB 表复制到不执行二进制日志的存储引擎。 如果尝试将 NDB Cluster 复制到使用不处理自身二进制日志的存储引擎的副本,复制过程将因错误 无法进行二进制日志记录... 语句无法以原子方式写入,因为涉及多个引擎且至少一个引擎自带日志记录 (错误 1595) 而中止。可以通过以下一种方法解决此问题:Replicating NDB tables to a storage engine that does not perform binary logging. If you attempt to replicate from an NDB Cluster to a replica that uses a storage engine that does not handle its own binary logging, the replication process aborts with the error Binary logging not possible ... Statement cannot be written atomically since more than one engine involved and at least one engine is self-logging (Error 1595). It is possible to work around this issue in one of the following ways:
关闭副本上的二进制日志记录。 这可以通过设置
sql_log_bin = 0来实现。Turn off binary logging on the replica. This can be accomplished by settingsql_log_bin = 0.更改 mysql.ndb_apply_status 表使用的存储引擎。 让这个表使用不处理自身二进制日志的引擎也可以消除冲突。这可以通过在副本上执行类似
ALTER TABLE mysql.ndb_apply_status ENGINE=MyISAM的语句来完成。当在副本上使用除NDB之外的存储引擎时,这样做是安全的,因为您不需要担心保持多个副本的同步。Change the storage engine used for the mysql.ndb_apply_status table. Causing this table to use an engine that does not handle its own binary logging can also eliminate the conflict. This can be done by issuing a statement such asALTER TABLE mysql.ndb_apply_status ENGINE=MyISAMon the replica. It is safe to do this when using a storage engine other thanNDBon the replica, since you do not need to worry about keeping multiple replicas synchronized.在从库上过滤对 mysql.ndb_apply_status 表的更改。 这可以通过使用
--replicate-ignore-table=mysql.ndb_apply_status启动从库来实现。如果你希望其他表也被复制忽略,你可能希望使用相应的--replicate-wild-ignore-table选项。Filter out changes to the mysql.ndb_apply_status table on the replica. This can be done by starting the replica with--replicate-ignore-table=mysql.ndb_apply_status. If you need for other tables to be ignored by replication, you might wish to use an appropriate--replicate-wild-ignore-tableoption instead.
Important
在从一个 NDB 集群复制到另一个 NDB 集群时,您 不 应该禁用 mysql.ndb_apply_status 的复制或二进制日志,也不应更改此表使用的存储引擎。详情请参见 NDB 集群间复制的复制和二进制日志过滤规则。You should not disable replication or
binary logging of mysql.ndb_apply_status or
change the storage engine used for this table when replicating
from one NDB Cluster to another. See
Replication and binary log filtering rules with replication between NDB
Clusters,
for details.
从 NDB 到非事务性存储引擎的复制。 当从 NDB 复制到非事务性存储引擎(例如 MyISAM)时,复制 INSERT ...
ON DUPLICATE KEY UPDATE 语句可能会遇到不必要的重复键错误。你可以使用 --ndb-log-update-as-write=0 来抑制这些错误,它会强制将更新记录为写入,而不是作为更新。Replication from NDB to a nontransactional storage engine.
When replicating from NDB to a
nontransactional storage engine such as
MyISAM, you may encounter
unnecessary duplicate key errors when replicating
INSERT ...
ON DUPLICATE KEY UPDATE statements. You can suppress
these by using
--ndb-log-update-as-write=0,
which forces updates to be logged as writes, rather than as
updates.
NDB 复制与文件系统加密(TDE)。 使用加密文件系统对 NDB 复制没有任何影响。以下所有场景都是支持的:NDB Replication and File System Encryption (TDE). The use of an encrypted filesystem does not have any effect on NDB Replication. All of the following scenarios are supported:
将拥有加密文件系统的 NDB 集群复制到文件系统未加密的 NDB 集群。Replication of an NDB Cluster having an encrypted file system to an NDB Cluster whose file system is not encrypted.
将文件系统未加密的 NDB 集群复制到文件系统已加密的 NDB 集群。Replication of an NDB Cluster whose file system is not encrypted to an NDB Cluster whose file system is encrypted.
将文件系统已加密的 NDB 集群复制到使用未加密
InnoDB表的独立 MySQL 服务器。Replication of an NDB Cluster whose file system is encrypted to a standalone MySQL server usingInnoDBtables which are not encrypted.将文件系统未加密的 NDB 集群复制到使用带文件系统加密的
InnoDB表的独立 MySQL 服务器。Replication of an NDB Cluster with an unencrypted file system to a standalone MySQL server usingInnoDBtables with file sytem encryption.
NDB 集群之间复制时的复制和二进制日志过滤规则。 如果您使用了任何选项 --replicate-do-*、--replicate-ignore-*、--binlog-do-db 或 --binlog-ignore-db 来过滤要复制的数据库或表,则必须注意不要阻止 mysql.ndb_apply_status 的复制或二进制日志记录,这是 NDB 集群之间复制正常运行所必需的。特别是,您必须牢记以下几点:Replication and binary log filtering rules with replication between NDB
Clusters.
If you are using any of the options
--replicate-do-*,
--replicate-ignore-*,
--binlog-do-db, or
--binlog-ignore-db to filter
databases or tables being replicated, you must take care not to
block replication or binary logging of the
mysql.ndb_apply_status, which is required for
replication between NDB Clusters to operate properly. In
particular, you must keep in mind the following:
使用
--replicate-do-db=(并且不使用其他db_name--replicate-do-*或--replicate-ignore-*选项)意味着 只有 数据库db_name中的表会被复制。在这种情况下,你还应该使用--replicate-do-db=mysql、--binlog-do-db=mysql或--replicate-do-table=mysql.ndb_apply_status来确保在从服务器上填充mysql.ndb_apply_status。Using--replicate-do-db=(and no otherdb_name--replicate-do-*or--replicate-ignore-*options) means that only tables in databasedb_nameare replicated. In this case, you should also use--replicate-do-db=mysql,--binlog-do-db=mysql, or--replicate-do-table=mysql.ndb_apply_statusto ensure thatmysql.ndb_apply_statusis populated on replicas.Using
--binlog-do-db=(and no otherdb_name--binlog-do-dboptions) means that changes 生成的值 to tables in databasedb_nameare written to the binary log. In this case, you should also use--replicate-do-db=mysql,--binlog-do-db=mysql,或--replicate-do-table=mysql.ndb_apply_statusto ensure thatmysql.ndb_apply_statusis populated on replicas.Using--binlog-do-db=(and no otherdb_name--binlog-do-dboptions) means that changes only to tables in databasedb_nameare written to the binary log. In this case, you should also use--replicate-do-db=mysql,--binlog-do-db=mysql, or--replicate-do-table=mysql.ndb_apply_statusto ensure thatmysql.ndb_apply_statusis populated on replicas.使用
--replicate-ignore-db=mysql意味着mysql数据库中的任何表都不会被复制。在这种情况下,你还应该使用--replicate-do-table=mysql.ndb_apply_status来确保mysql.ndb_apply_status被复制。Using--replicate-ignore-db=mysqlmeans that no tables in themysqldatabase are replicated. In this case, you should also use--replicate-do-table=mysql.ndb_apply_statusto ensure thatmysql.ndb_apply_statusis replicated.使用
--binlog-ignore-db=mysql意味着对mysql数据库中表的任何更改都不会写入二进制日志。在这种情况下,你还应使用--replicate-do-table=mysql.ndb_apply_status来确保mysql.ndb_apply_status能够被复制。Using--binlog-ignore-db=mysqlmeans that no changes to tables in themysqldatabase are written to the binary log. In this case, you should also use--replicate-do-table=mysql.ndb_apply_statusto ensure thatmysql.ndb_apply_statusis replicated.
你还应记住,每条复制规则都需要满足以下条件:You should also remember that each replication rule requires the following:
它自己的
--replicate-do-*或--replicate-ignore-*选项,并且多个规则不能在单个复制过滤选项中表达。有关这些规则的信息,请参见 第 19.1.6 节,“复制和二进制日志选项及变量”。Its own--replicate-do-*or--replicate-ignore-*option, and that multiple rules cannot be expressed in a single replication filtering option. For information about these rules, see Section 19.1.6, “Replication and Binary Logging Options and Variables”.它自己的
--binlog-do-db或--binlog-ignore-db选项,并且多个规则不能在单个二进制日志过滤选项中表达。有关这些规则的信息,请参见 第 7.4.4 节,“二进制日志”。Its own--binlog-do-dbor--binlog-ignore-dboption, and that multiple rules cannot be expressed in a single binary log filtering option. For information about these rules, see Section 7.4.4, “The Binary Log”.
如果您正在将 NDB 集群复制到使用除 NDB 之外的存储引擎的副本,则前面给出的考虑事项可能不适用,如本节其他地方所讨论。If you are replicating an NDB Cluster to a replica that uses a
storage engine other than NDB, the
considerations just given previously may not apply, as discussed
elsewhere in this section.
NDB 集群复制与 IPv6。 在 NDB 8.4 中,所有类型的 NDB 集群节点都支持 IPv6;这包括管理节点、数据节点以及 API 或 SQL 节点。NDB Cluster Replication and IPv6. All types of NDB Cluster nodes support IPv6 in NDB 8.4; this includes management nodes, data nodes, and API or SQL nodes.
Note
在 NDB 8.4 中,如果您不打算为任何 NDB 集群节点使用 IPv6 地址,可以在 Linux 内核中禁用 IPv6 支持。In NDB 8.4, you can disable IPv6 support in the Linux kernel if you do not intend to use IPv6 addressing for any NDB Cluster nodes.
属性提升与降级。 NDB 集群复制支持属性提升与降级。后者的实现区分了有损和无损类型转换,并且可以通过设置系统变量的全局值replica_type_conversions来控制它们在副本上的使用。Attribute promotion and demotion.
NDB Cluster Replication includes support for attribute promotion
and demotion. The implementation of the latter distinguishes
between lossy and non-lossy type conversions, and their use on
the replica can be controlled by setting the global value of the
system variable
replica_type_conversions.
有关 NDB 集群中属性提升与降级的更多信息,请参见 基于行的复制:属性提升与降级。For more information about attribute promotion and demotion in NDB Cluster, see Row-based replication: attribute promotion and demotion.
NDB,与 InnoDB 或 MyISAM 不同,不会将虚拟列的更改写入二进制日志;然而,这对 NDB 集群复制或 NDB 与其他存储引擎之间的复制没有不利影响。对存储生成列的更改会被记录。NDB, unlike InnoDB
or MyISAM, does not write changes to
virtual columns to the binary log; however, this has no
detrimental effects on NDB Cluster Replication or replication
between NDB and other storage engines. Changes
to stored generated columns are logged.